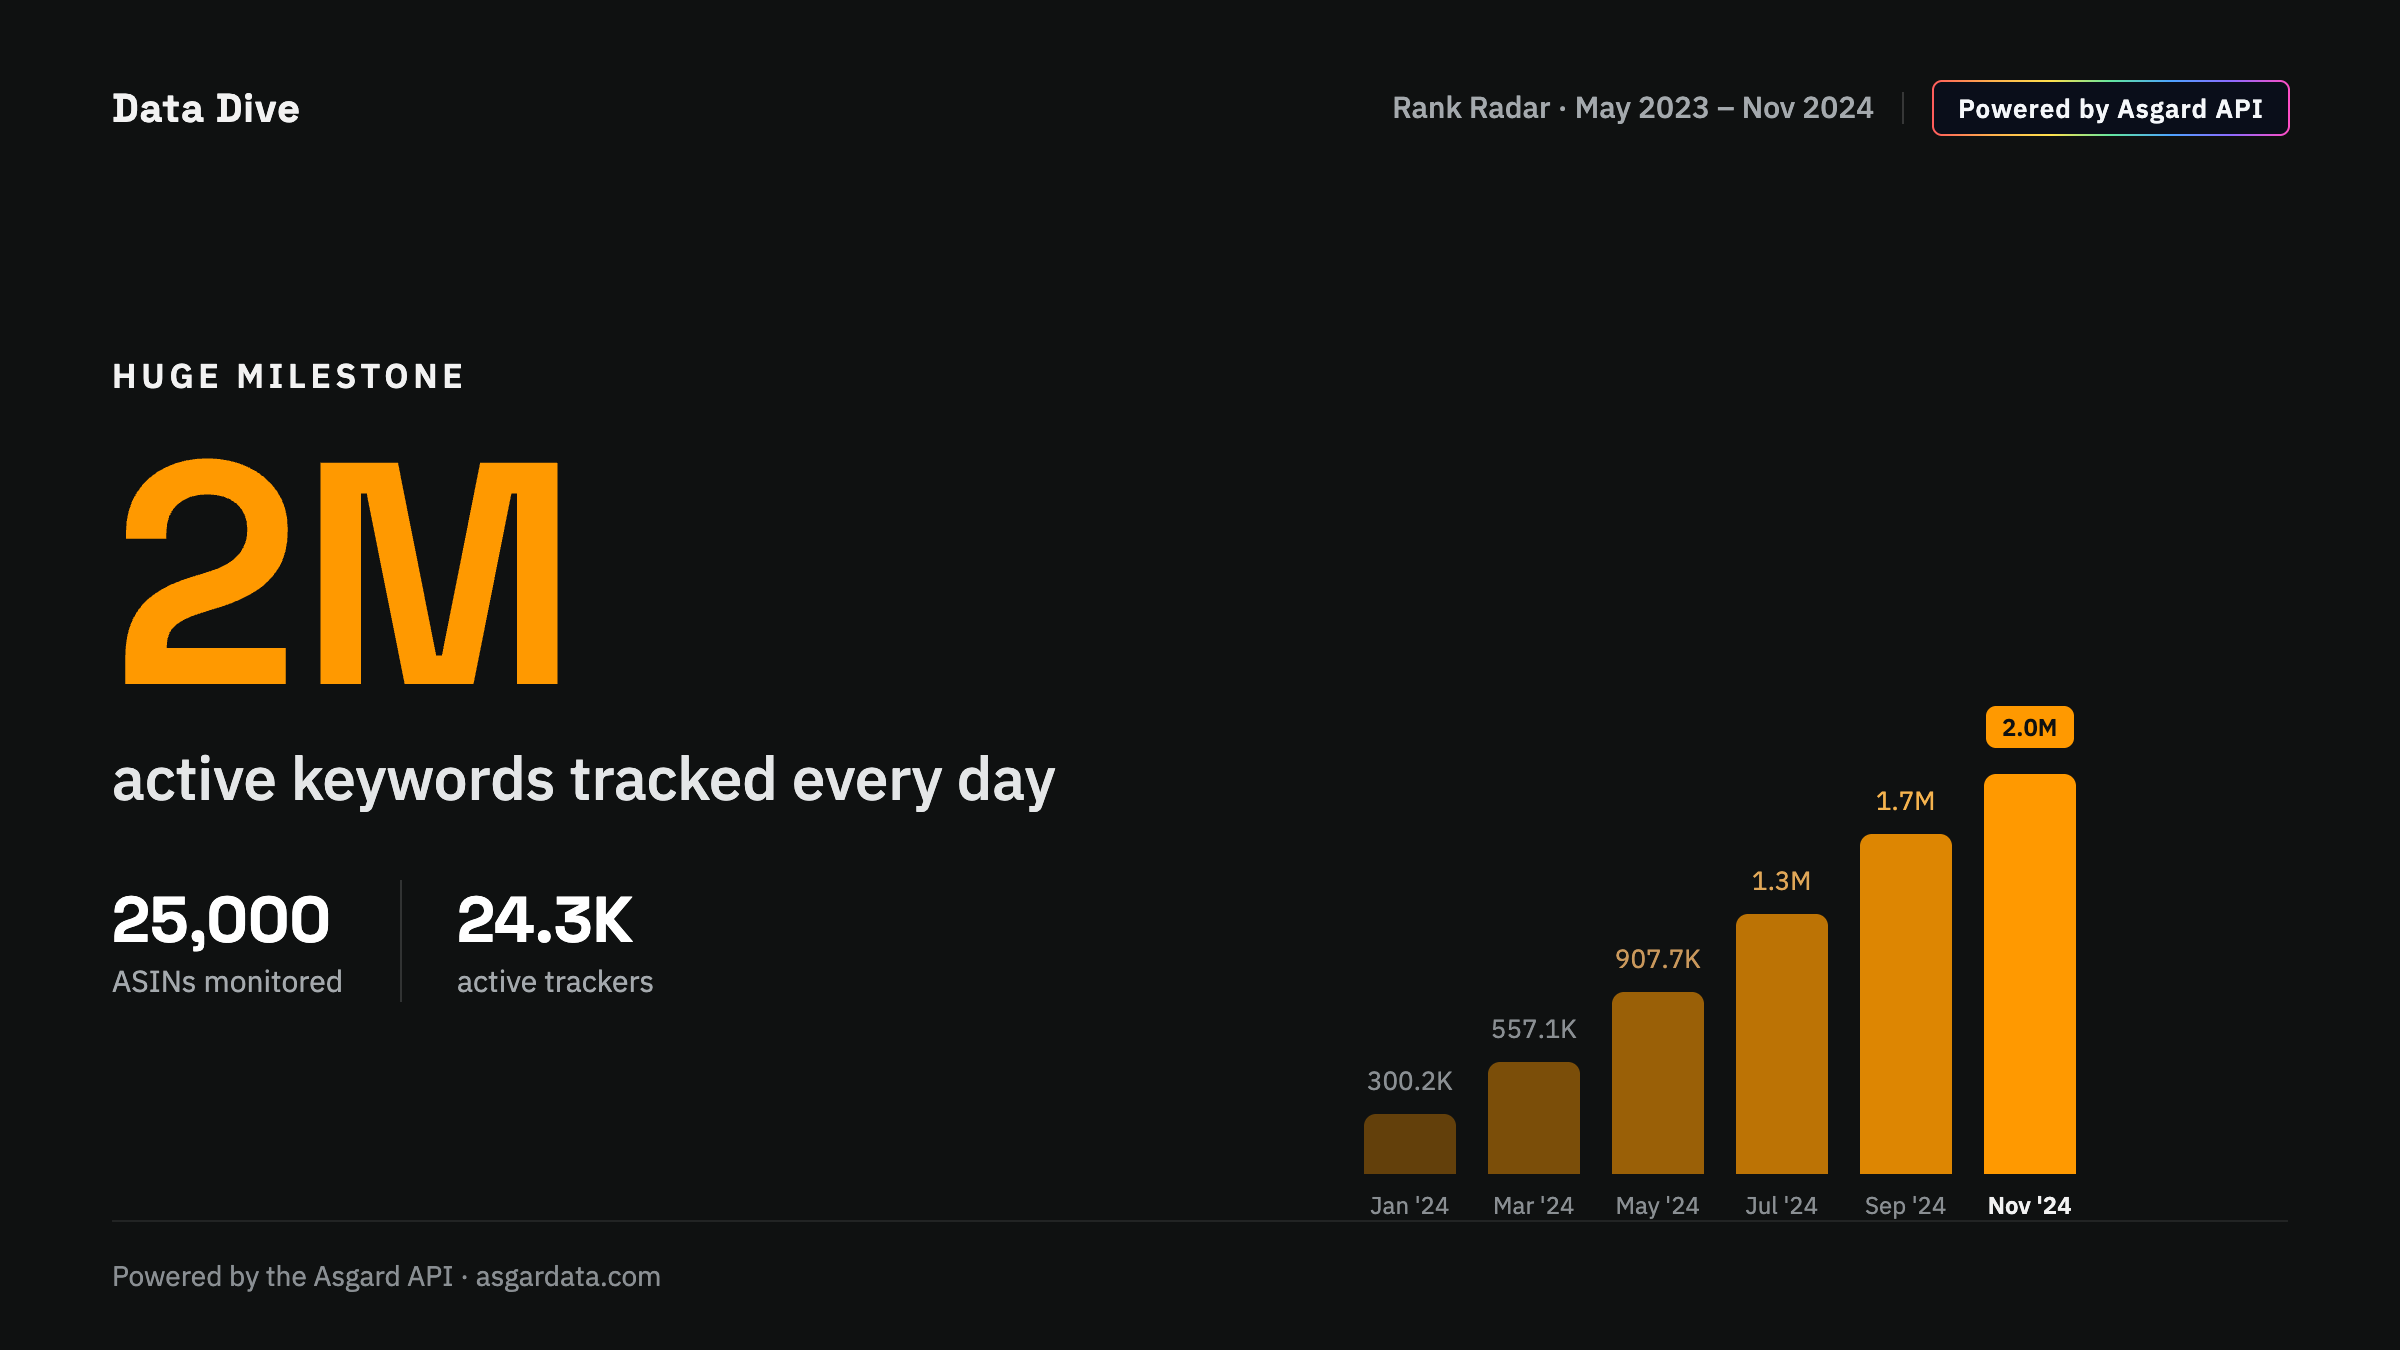
Datadive used our scraping API to build one of the highest-scale daily Amazon keyword rank trackers in the industry — 2M+ active keywords tracked every day across 25,000+ ASINs and 24.3K active trackers. Scraping Amazon is easy. Scraping it accurately, daily, at that volume is the hard part — and that's exactly the problem we solved for them.
Quick answer
⦿ Who: Datadive — one of the first Amazon tools to give our very first v0 scraping API a chance.
⦿ What they built: a daily keyword rank tracker scaling from 300K to 2M+ keywords/day (May 2023 → Nov 2024).
⦿ The hard part: data accuracy at scale, not raw request volume.
⦿ Since then: after many iterations, Asgard is now also one of the fastest Amazon scraping APIs on the market.
Scraping Amazon is easy. Scraping accurately is hard.
Datadive was the only Amazon tool that gave our first v0 Amazon scraping API a chance. The pains they had back then are still the exact same pains every tool trying to scrape Amazon runs into today. It all comes down to one word: accuracy.
The four things that quietly wreck rank data:
- Type of IPs used — results are inaccurate via cheap datacenter IPs. Residential or nothing.
- Retry mechanisms — you need them to make sure you extract 100% of the sponsored-ranked ASINs, not the partial set a single scrape returns.
- Location matching across SERP pagination — page 1 and page 2 have to come from the same locked location or the ranking is meaningless.
- Geolocation targeting — buybox and organic rank results change by zip code, so targeting has to be deliberate, not random.
And you have to do ALL of this while staying cost-effective enough to scale to millions of daily keywords. That's the tightrope.
Why it's even harder now
This work is even more appreciated today because of AI. Amazon has cranked up its antibotting measures and blockage rates to deal with the AI scraping wave. That means:
⤷ higher costs
⤷ lower success rates
⤷ more IP spend to get the same accurate result
A normal scraper can't survive Amazon anymore. Period. You need big guns to keep 2M+ daily keywords accurate.
The growth curve
Datadive's daily keyword volume on Asgard, month over month:
- Jan ’24 — 300.2K
- Mar ’24 — 557.1K
- May ’24 — 907.7K
- Jul ’24 — 1.3M
- Sep ’24 — 1.7M
- Nov ’24 — 2.0M
That's the kind of curve you only sustain when the data underneath is accurate enough to trust and cheap enough to scale.
Since then: one of the fastest Amazon scraping APIs on the market
Here's the update. After MANNNNY iterations since we first started with Datadive, we didn't just stay accurate — we also became one of the fastest Amazon scraping APIs in the market. Same residential-grade accuracy, same full sponsored-rank capture, same zip-locked results — now delivered fast enough to power real-time and daily workloads at scale.
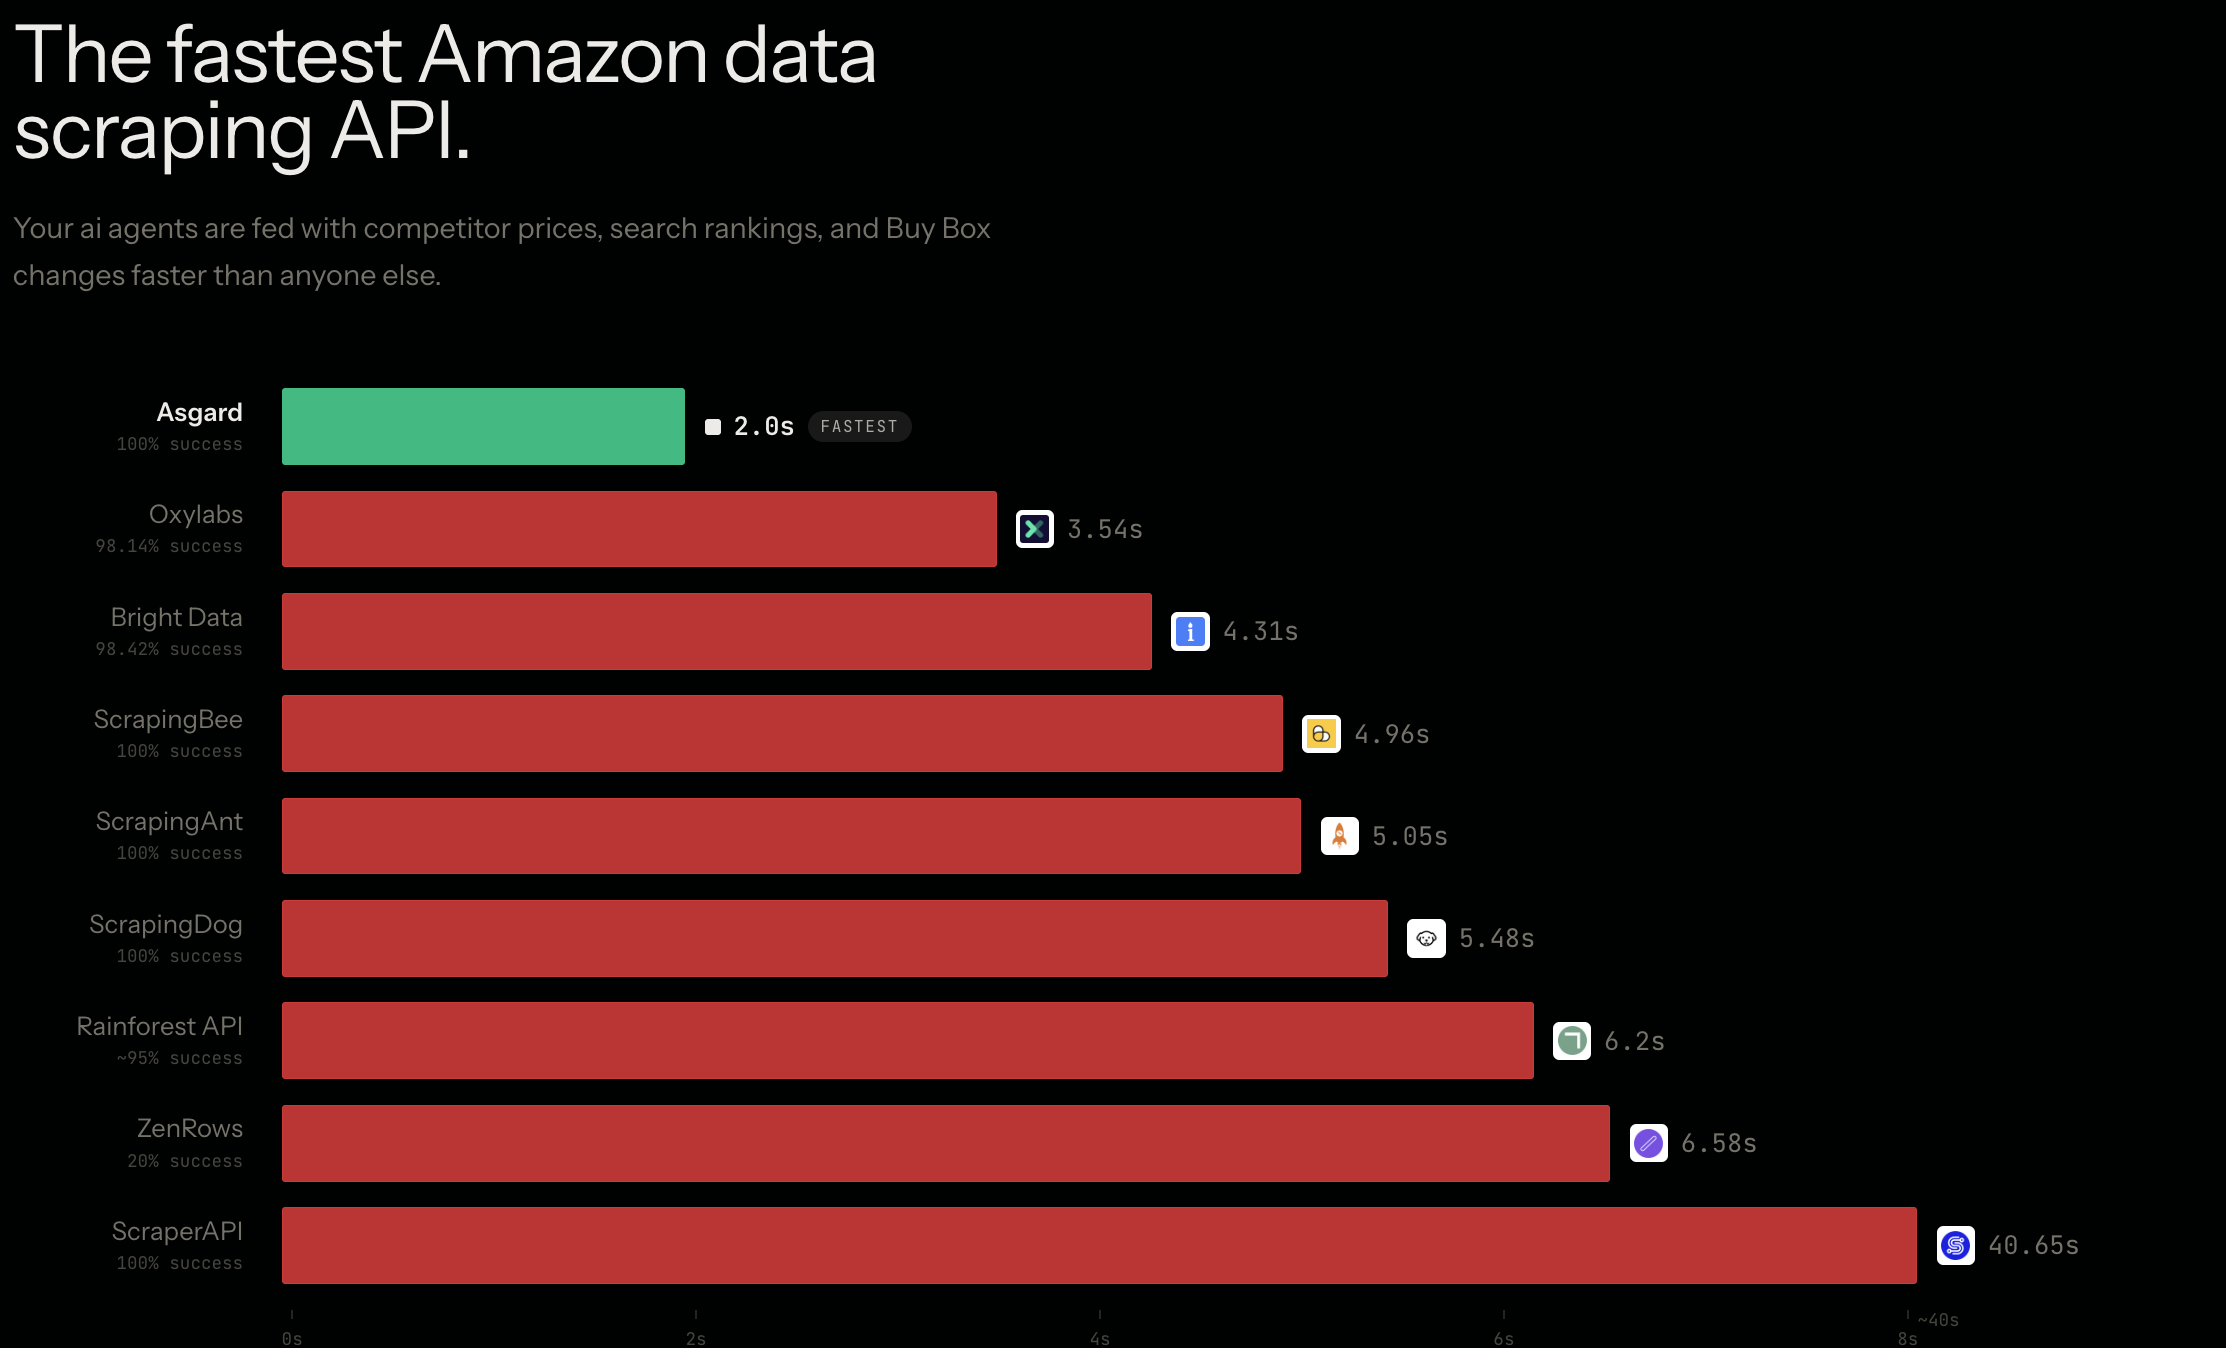
In head-to-head benchmarks Asgard returns a full Amazon result in 2.0s at 100% success — versus 3.54s for Oxylabs, 4.31s for Bright Data, and 4.96s–6.58s for the rest of the field, with ScraperAPI trailing at 40.65s. Fastest response, top-tier success rate.
Accurate AND fast. That's the combination almost nobody in Amazon scraping actually ships.
FAQ
How many keywords does Datadive track per day on Asgard?
2M+ active keywords every day, across 25,000+ ASINs and 24.3K active trackers.
Why not just use datacenter IPs to keep it cheap?
Because DC IPs return inaccurate ranks, prices, and buybox data. Residential proxies are the only way to match what a real shopper sees.
Why do you need retry mechanisms for sponsored ranks?
Sponsored/ad ASINs don't all load on the first request. Without retries you underreport the competition on every keyword.
Is Asgard fast or just accurate?
Both. Accuracy came first with Datadive; since then we've become one of the fastest Amazon scraping APIs on the market.